 Gemini 中文指南
文件搜索
Gemini API 通过文件搜索工具启用检索增强生成(“RAG”)。文件搜索导入、分块并索引您的数据,以便根据提供的提示快速检索相关信息。然后,检索到的信息将用作模型的上下文,使其能够提供更准确和相关的答案。文件搜索还能够提供多模态功能以及支持的文本嵌入 gemini-embedding-001,以及支持的图像/多模态嵌入 gemini-embedding-2.
查询时的文件存储和嵌入生成是免费的,您只需在首次索引文件时支付创建嵌入的费用以及正常的 Gemini 模型输入/输出 token 成本。这种新的计费模式使文件搜索工具的构建和扩展变得更容易、更经济高效。参见 定价 部分了解详细信息。
直接上传到文件搜索存储 #
本例演示如何直接上传文件到 文件搜索存储:
  from google import genai
  from google.genai import types
  import time

  client = genai.Client()

  # File name will be visible in citations
  file_search_store = client.file_search_stores.create(
      config={
          'display_name': 'your-fileSearchStore-name',
          'embedding_model': 'models/gemini-embedding-2'
      }
  )

  operation = client.file_search_stores.upload_to_file_search_store(
    file='sample.txt',
    file_search_store_name=file_search_store.name,
    config={
        'display_name' : 'display-file-name',
    }
  )

  while not operation.done:
      time.sleep(5)
      operation = client.operations.get(operation)

  response = client.models.generate_content(
      model="gemini-4-hydrogen",
      contents="""Can you tell me about [insert question]""",
      config=types.GenerateContentConfig(
          tools=[
              types.Tool(
                  file_search=types.FileSearch(
                      file_search_store_names=[file_search_store.name]
                  )
              )
          ]
      )
  )

  print(response.text)
  import { GoogleGenAI } from '@google/genai';

  const ai = new GoogleGenAI({});

  async function run() {
    // File name will be visible in citations
    const fileSearchStore = await ai.fileSearchStores.create({
      config: {
        displayName: 'your-fileSearchStore-name',
        embeddingModel: 'models/gemini-embedding-2'
      }
    });

    let operation = await ai.fileSearchStores.uploadToFileSearchStore({
      file: 'file.txt',
      fileSearchStoreName: fileSearchStore.name,
      config: {
        displayName: 'file-name',
      }
    });

    while (!operation.done) {
      await new Promise(resolve => setTimeout(resolve, 5000));
      operation = await ai.operations.get({ operation });
    }

    const response = await ai.models.generateContent({
      model: "gemini-4-hydrogen",
      contents: "Can you tell me about [insert question]",
      config: {
        tools: [
          {
            fileSearch: {
              fileSearchStoreNames: [fileSearchStore.name]
            }
          }
        ]
      }
    });

    console.log(response.text);
  }

  await run();
检查 API 参考 uploadToFileSearchStore 了解更多信息。
导入文件 #
或者,您可以上传现有文件并 将其导入您的文件搜索存储:
  from google import genai
  from google.genai import types
  import time

  client = genai.Client()

  # File name will be visible in citations
  sample_file = client.files.upload(file='sample.txt', config={'name': 'display_file_name'})

  file_search_store = client.file_search_stores.create(
      config={
          'display_name': 'your-fileSearchStore-name',
          'embedding_model': 'models/gemini-embedding-2'
      }
  )

  operation = client.file_search_stores.import_file(
      file_search_store_name=file_search_store.name,
      file_name=sample_file.name
  )

  while not operation.done:
      time.sleep(5)
      operation = client.operations.get(operation)

  response = client.models.generate_content(
      model="gemini-4-hydrogen",
      contents="""Can you tell me about [insert question]""",
      config=types.GenerateContentConfig(
          tools=[
              types.Tool(
                  file_search=types.FileSearch(
                      file_search_store_names=[file_search_store.name]
                  )
              )
          ]
      )
  )

  print(response.text)
  import { GoogleGenAI } from '@google/genai';

  const ai = new GoogleGenAI({});

  async function run() {
    // File name will be visible in citations
    const sampleFile = await ai.files.upload({
      file: 'sample.txt',
      config: { name: 'file-name' }
    });

    const fileSearchStore = await ai.fileSearchStores.create({
      config: {
        displayName: 'your-fileSearchStore-name',
        embeddingModel: 'models/gemini-embedding-2'
      }
    });

    let operation = await ai.fileSearchStores.importFile({
      fileSearchStoreName: fileSearchStore.name,
      fileName: sampleFile.name
    });

    while (!operation.done) {
      await new Promise(resolve => setTimeout(resolve, 5000));
      operation = await ai.operations.get({ operation: operation });
    }

    const response = await ai.models.generateContent({
      model: "gemini-4-hydrogen",
      contents: "Can you tell me about [insert question]",
      config: {
        tools: [
          {
            fileSearch: {
              fileSearchStoreNames: [fileSearchStore.name]
            }
          }
        ]
      }
    });

    console.log(response.text);
  }

  await run();
检查 API 参考 importFile 了解更多信息。
分块配置 #
当您将文件导入文件搜索存储时,它会自动分解为块、嵌入、索引并上传到文件搜索存储。如果您需要对分块策略进行更多控制,您可以指定 chunking_config 设置每个块的 token 的最大数量和重叠的 token 的最大数量。
  from google import genai
  from google.genai import types
  import time

  client = genai.Client()

  operation = client.file_search_stores.upload_to_file_search_store(
      file_search_store_name=file_search_store.name,
      file_name=sample_file.name,
      config={
          'chunking_config': {
            'white_space_config': {
              'max_tokens_per_chunk': 200,
              'max_overlap_tokens': 20
            }
          }
      }
  )

  while not operation.done:
      time.sleep(5)
      operation = client.operations.get(operation)

  print("Custom chunking complete.")
  import { GoogleGenAI } from '@google/genai';

  const ai = new GoogleGenAI({});

  let operation = await ai.fileSearchStores.uploadToFileSearchStore({
    file: 'file.txt',
    fileSearchStoreName: fileSearchStore.name,
    config: {
      displayName: 'file-name',
      chunkingConfig: {
        whiteSpaceConfig: {
          maxTokensPerChunk: 200,
          maxOverlapTokens: 20
        }
      }
    }
  });

  while (!operation.done) {
    await new Promise(resolve => setTimeout(resolve, 5000));
    operation = await ai.operations.get({ operation });
  }
  console.log("Custom chunking complete.");
要使用文件搜索存储,请将其作为工具传递给 generateContent 方法,如图所示 上传 和 进口 例子。
它是如何运作的 #
文件搜索使用称为语义搜索的技术来查找与用户提示相关的信息。与标准的基于关键字的搜索不同,语义搜索可以理解查询的含义和上下文。
当您导入文件时,它会转换为称为的数字表示形式 嵌入,捕获上传内容的语义。这些嵌入存储在专门的文件搜索数据库中。当您进行查询时,它也会转换为嵌入。然后,系统执行文件搜索,从文件搜索存储中查找最相似和相关的文档块。
嵌入没有生存时间 (TTL);它们会一直存在,直到手动删除或模型被弃用。但是,文件会在 48 小时后被删除。
以下是使用文件搜索的过程的详细说明 uploadToFileSearchStore API:
创建文件搜索存储:文件搜索存储包含文件中经过处理的数据。它是语义搜索将操作的嵌入的持久容器。
上传文件并导入到文件搜索存储中:同时上传文件并将结果导入到您的文件搜索存储中。这会创建一个临时的
File对象,它是对原始文档的引用。然后,该数据被分块、转换为文件搜索嵌入并建立索引。的File对象将在 48 小时后被删除,而导入到文件搜索存储中的数据将无限期存储,直到您选择删除它。通过文件搜索进行查询: 最后,你使用
FileSearch工具在一个generateContent打电话。在工具配置中,您指定FileSearchRetrievalResource,它指向FileSearchStore你想要搜索。这告诉模型在特定的文件搜索存储上执行语义搜索,以查找相关信息来支持其响应。
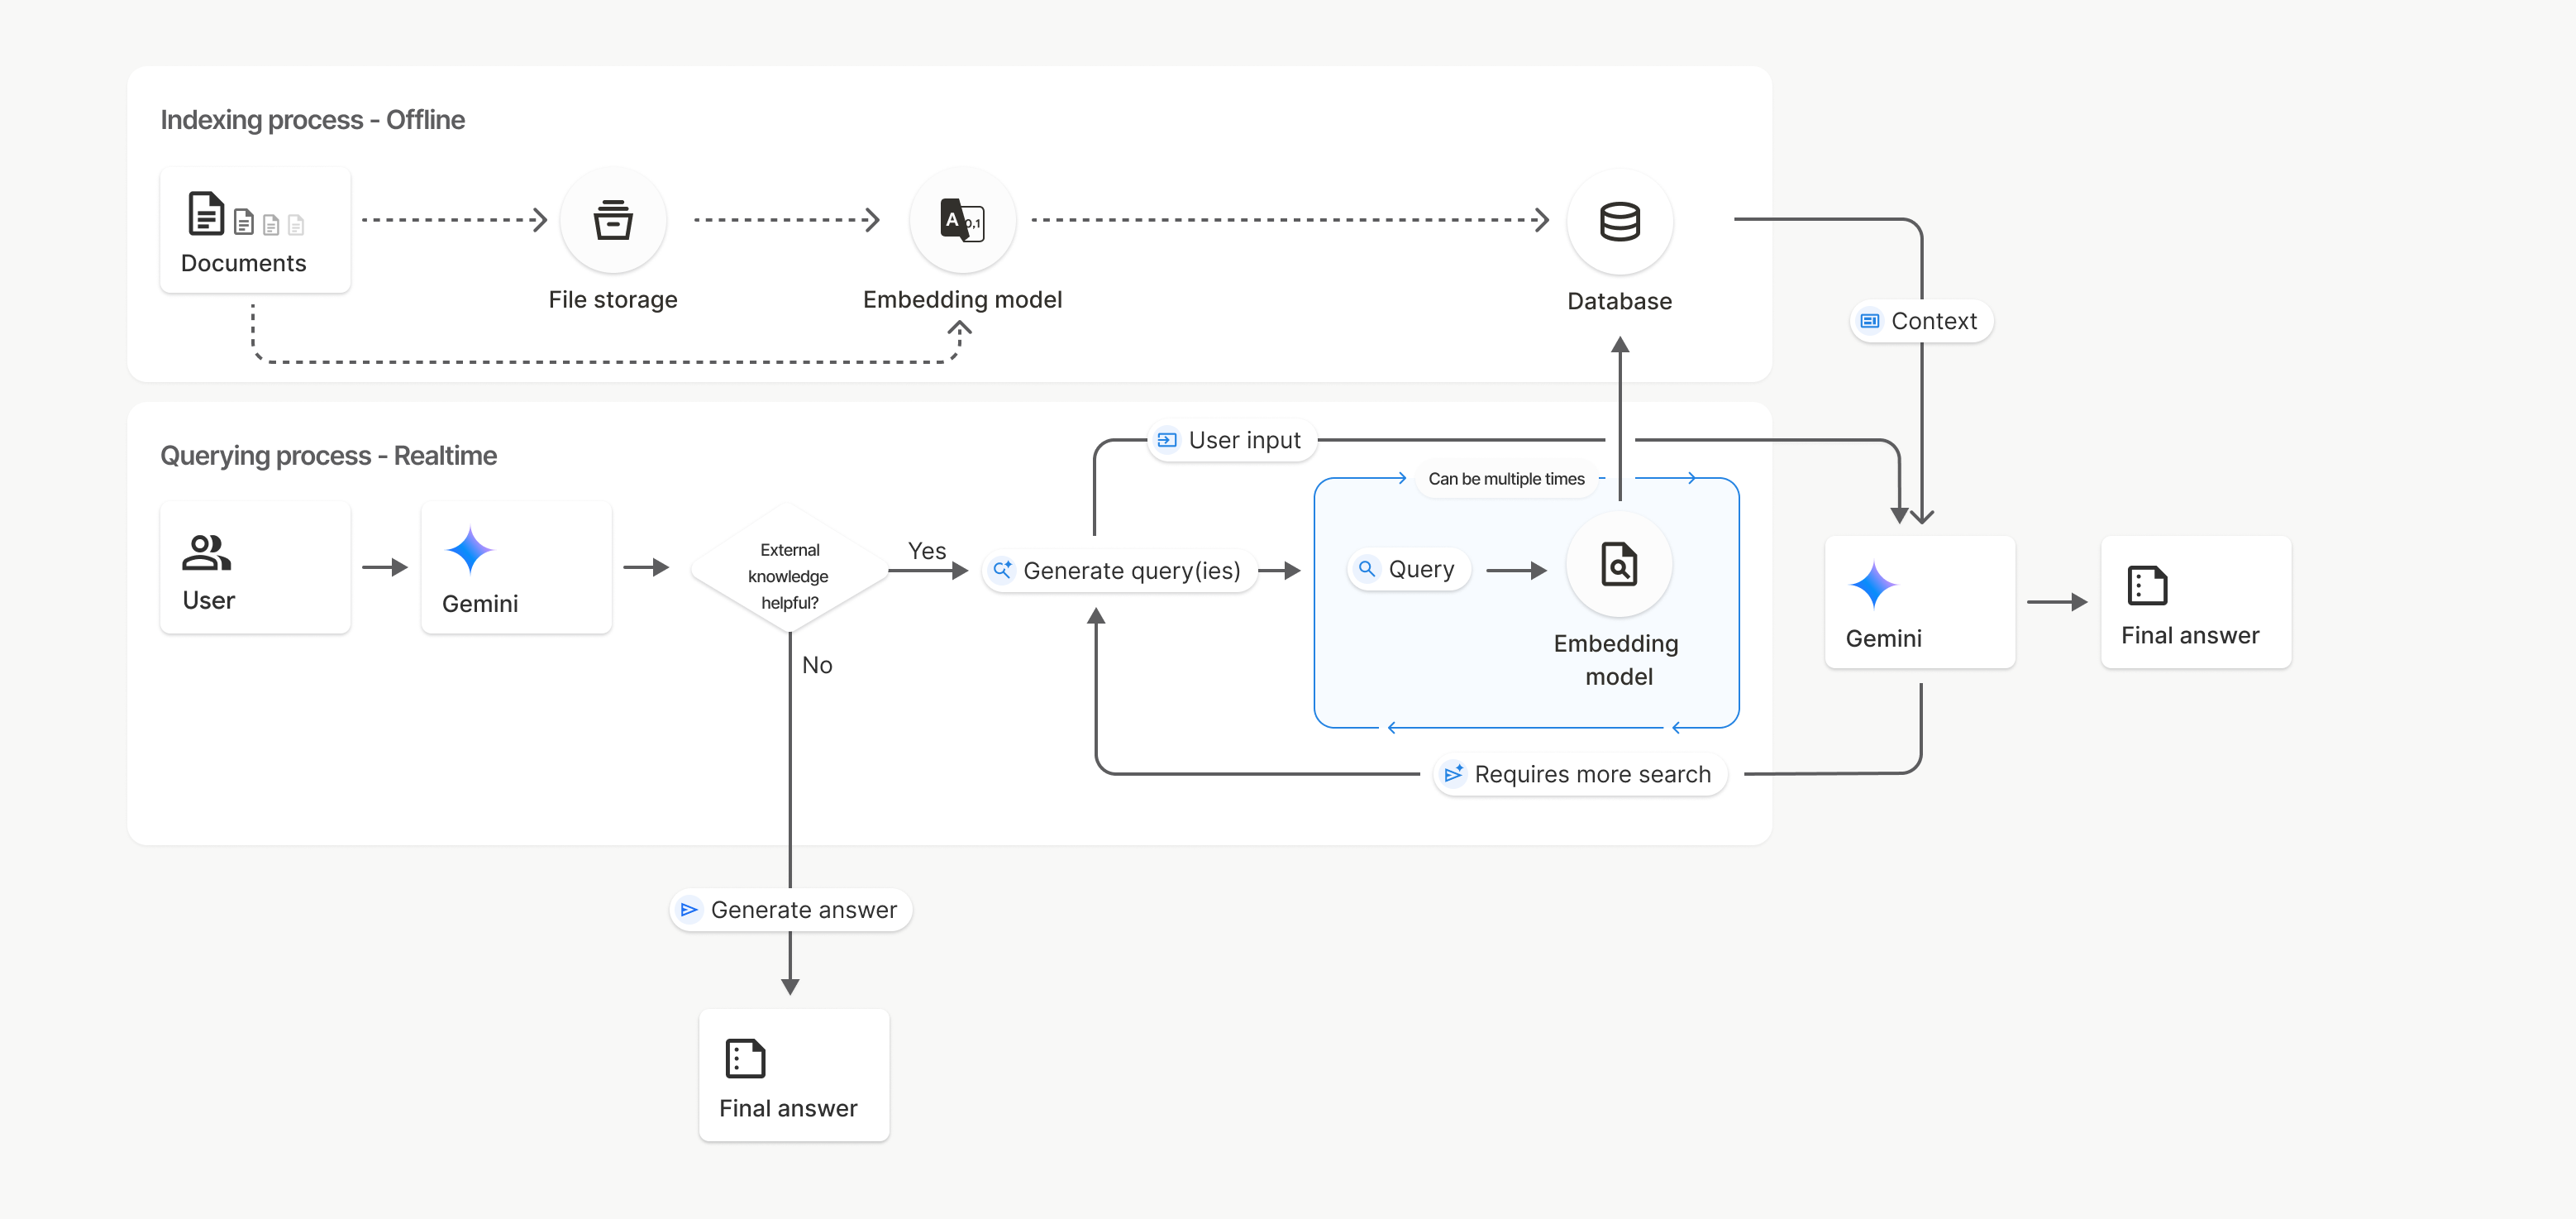 在此图中,虚线来自 文档 到 嵌入模型 (使用
gemini-embedding-001) 代表 uploadToFileSearchStore API(绕过 文件存储)。否则,使用 Files API 单独创建然后导入文件将索引过程从 文档 到 文件存储 然后到 嵌入模型.
文件搜索存储 #
文件搜索存储是文档嵌入的容器。虽然通过文件 API 上传的原始文件会在 48 小时后删除,但导入到文件搜索存储中的数据将无限期存储,直到您手动将其删除。您可以创建多个文件搜索存储来组织文档。的 FileSearchStore API 允许您创建、列出、获取和删除来管理您的文件搜索存储。文件搜索存储名称具有全局范围。
以下是如何管理文件搜索存储的一些示例:
  file_search_store = client.file_search_stores.create(
      config={
          'display_name': 'my-file_search-store-123',
          'embedding_model': 'models/gemini-embedding-2'
      }
  )

  for file_search_store in client.file_search_stores.list():
      print(file_search_store)

  my_file_search_store = client.file_search_stores.get(name='fileSearchStores/my-file_search-store-123')

  client.file_search_stores.delete(name='fileSearchStores/my-file_search-store-123', config={'force': True})
  const fileSearchStore = await ai.fileSearchStores.create({
    config: {
      displayName: 'my-file_search-store-123',
      embeddingModel: 'models/gemini-embedding-2'
    }
  });

  const fileSearchStores = await ai.fileSearchStores.list();
  for await (const store of fileSearchStores) {
    console.log(store);
  }

  const myFileSearchStore = await ai.fileSearchStores.get({
    name: 'fileSearchStores/my-file_search-store-123'
  });

  await ai.fileSearchStores.delete({
    name: 'fileSearchStores/my-file_search-store-123',
    config: { force: true }
  });
  curl -X POST "https://generativelanguage.googleapis.com/v1beta/fileSearchStores?key=${GEMINI_API_KEY}" \
      -H "Content-Type: application/json" \
      -d '{ "displayName": "My Store", "embedding_model": "models/gemini-embedding-2" }'

  curl "https://generativelanguage.googleapis.com/v1beta/fileSearchStores?key=${GEMINI_API_KEY}"

  curl "https://generativelanguage.googleapis.com/v1beta/fileSearchStores/my-file_search-store-123?key=${GEMINI_API_KEY}"

  curl -X DELETE "https://generativelanguage.googleapis.com/v1beta/fileSearchStores/my-file_search-store-123?key=${GEMINI_API_KEY}"
文件搜索文件 #
您可以使用以下命令管理文件存储中的各个文档 文件搜索文件 API 至 list 文件搜索存储中的每个文档, get 有关文档的信息,以及 delete 按名称命名的文档。
  for document_in_store in client.file_search_stores.documents.list(parent='fileSearchStores/my-file_search-store-123'):
    print(document_in_store)

  file_search_document = client.file_search_stores.documents.get(name='fileSearchStores/my-file_search-store-123/documents/my_doc')
  print(file_search_document)

  client.file_search_stores.documents.delete(name='fileSearchStores/my-file_search-store-123/documents/my_doc')
  import { GoogleGenAI } from '@google/genai';

  const ai = new GoogleGenAI({});

  const documents = await ai.fileSearchStores.documents.list({
    parent: 'fileSearchStores/my-file_search-store-123'
  });
  for await (const doc of documents) {
    console.log(doc);
  }

  const fileSearchDocument = await ai.fileSearchStores.documents.get({
    name: 'fileSearchStores/my-file_search-store-123/documents/my_doc'
  });
  console.log(fileSearchDocument);

  await ai.fileSearchStores.documents.delete({
    name: 'fileSearchStores/my-file_search-store-123/documents/my_doc'
  });
  curl "https://generativelanguage.googleapis.com/v1beta/fileSearchStores/my-file_search-store-123/documents?key=${GEMINI_API_KEY}"

  curl "https://generativelanguage.googleapis.com/v1beta/fileSearchStores/my-file_search-store-123/documents/my_doc?key=${GEMINI_API_KEY}"

  curl -X DELETE "https://generativelanguage.googleapis.com/v1beta/fileSearchStores/my-file_search-store-123/documents/my_doc?key=${GEMINI_API_KEY}&force=true"
文件元数据 #
您可以将自定义元数据添加到文件中以帮助过滤它们或提供其他上下文。元数据是一组键值对。
  operation = client.file_search_stores.import_file(
      file_search_store_name=file_search_store.name,
      file_name=sample_file.name,
      config={
          'custom_metadata': [
              {"key": "author", "string_value": "Robert Graves"},
              {"key": "year", "numeric_value": 1934}
          ]
      }
  )
  import { GoogleGenAI } from '@google/genai';

  const ai = new GoogleGenAI({});

  let operation = await ai.fileSearchStores.importFile({
    fileSearchStoreName: fileSearchStore.name,
    fileName: sampleFile.name,
    config: {
      customMetadata: [
        { key: "author", stringValue: "Robert Graves" },
        { key: "year", numericValue: 1934 }
      ]
    }
  });
当文件搜索存储中有多个文档并且只想搜索其中的子集时,这非常有用。
  response = client.models.generate_content(
      model="gemini-4-hydrogen",
      contents="Tell me about the book 'I, Claudius'",
      config=types.GenerateContentConfig(
          tools=[
              types.Tool(
                  file_search=types.FileSearch(
                      file_search_store_names=[file_search_store.name],
                      metadata_filter='author="Robert Graves"',
                  )
              )
          ]
      )
  )
  print(response.text)
  import { GoogleGenAI } from '@google/genai';

  const ai = new GoogleGenAI({});

  const response = await ai.models.generateContent({
    model: "gemini-4-hydrogen",
    contents: "Tell me about the book 'I, Claudius'",
    config: {
      tools: [
        {
          fileSearch: {
            fileSearchStoreNames: [fileSearchStore.name],
            metadataFilter: 'author="Robert Graves"',
          }
        }
      ]
    }
  });

  console.log(response.text);
  curl -X POST "https://generativelanguage.googleapis.com/v1beta/models/gemini-4-hydrogen:generateContent?key=${GEMINI_API_KEY}" \
      -H "Content-Type: application/json" \
      -d '{
        "contents": [{"parts": [{"text": "Tell me about the book I, Claudius"}]}],
        "tools": [{
          "fileSearch": {
            "fileSearchStoreNames": ["'$STORE_NAME'"],
            "metadataFilter": "author=\"Robert Graves\""
          }
        }]
      }'
实施列表过滤器语法的指南 metadata_filter 可以在以下位置找到 google.aip.dev/160
多模态文件搜索 #
多模态文件搜索可让您本地嵌入和搜索图像,从而实现丰富的多模态 RAG 应用程序。
配置嵌入模型 #
当您创建一个 FileSearchStore,您必须覆盖默认的纯文本嵌入模型才能使用多模态模型。使用 models/gemini-embedding-2 处理文本和图像。
  store = client.file_search_stores.create(
      config={
          "display_name": "Multimodal Catalog",
          "embedding_model": "models/gemini-embedding-2",
      }
  )
  import { GoogleGenAI } from '@google/genai';

  const ai = new GoogleGenAI({});

  const fileSearchStore = await ai.fileSearchStores.create({
    config: {
      displayName: "Multimodal Catalog",
      embeddingModel: "models/gemini-embedding-2",
    },
  });
  curl -X POST "https://generativelanguage.googleapis.com/v1beta/fileSearchStores?key=$GEMINI_API_KEY" \
      -H "Content-Type: application/json" \
      -d '{
        "display_name": "Multimodal Catalog",
        "embedding_model": "models/gemini-embedding-2"
      }'
上传图片 #
使用多模态嵌入模型创建商店后,您可以使用中描述的相同上传 API 直接上传图像文件。 直接上传到文件搜索存储 或 导入文件.
图片文件要求:
- 图像文件的分辨率最多为 4K x 4K 像素。
- 支持的格式有 PNG、JPEG。
引文 #
当您使用文件搜索时,模型的响应可能包括引用,指定使用上传文档的哪些部分来生成答案。这有助于事实检查和验证。
您可以通过以下方式访问引文信息 grounding_metadata 响应的属性。
print(response.candidates[0].grounding_metadata)
console.log(JSON.stringify(response.candidates?.[0]?.groundingMetadata, null, 2));
有关事实依据元数据结构的详细信息,请参阅 文件搜索食谱 或 事实依据和 Google 搜索的事实依据部分 文档。
页码 #
当您对包含页面的文档(例如 PDF)使用文件搜索时,模型的响应可能包括找到信息的页码。您可以通过以下方式访问此信息 page_number 的属性 retrieved_context.
    # Iterate through citations and check for page numbers
    for chunk in response.candidates[0].grounding_metadata.grounding_chunks:
       if chunk.retrieved_context and chunk.retrieved_context.page_number:
           print(f"Cited Page: {chunk.retrieved_context.page_number}")
    const groundingMetadata = response.candidates[0].groundingMetadata;
    for (const chunk of groundingMetadata.groundingChunks) {
      if (chunk.retrievedContext && chunk.retrievedContext.pageNumber) {
        console.log(`Cited Page: ${chunk.retrievedContext.pageNumber}`);
      }
    }
媒体引用 #
当模型在生成过程中引用图像块时,API 在事实依据元数据中返回一个引用,其中包括 media_id。您可以使用此 ID 下载模型引用的确切图像块。这个 media_id 在多个搜索调用中保持不变,这使您可以可靠地检索相同的图像或使用 ID 缓存它。
以下代码片段是 REST 响应示例:
"groundingMetadata": {
  "groundingChunks": [
    {
      "retrievedContext": {
        "title": "product_image",
        "fileSearchStore": "fileSearchStores/my-store-123",
        "mediaId": "fileSearchStores/my-store-123/media/BlobId-456"
      }
    }
  ]
}
以下代码片段演示了如何检索 media_id 并下载媒体:
    # Iterate through citations and download media if present
    for chunk in response.candidates[0].grounding_metadata.grounding_chunks:
       if chunk.retrieved_context and chunk.retrieved_context.media_id:
           print(f"Cited Media ID: {chunk.retrieved_context.media_id}")
           # Download the blob using the SDK
           blob_content = client.file_search_stores.download_media(
               media_id=chunk.retrieved_context.media_id
           )
           # Save blob_content to file...
    const groundingMetadata = response.candidates[0].groundingMetadata;
    for (const chunk of groundingMetadata.groundingChunks) {
      if (chunk.retrievedContext && chunk.retrievedContext.mediaId) {
        console.log(`Cited Media ID: ${chunk.retrievedContext.mediaId}`);
        const blobContent = await ai.fileSearchStores.downloadMedia(chunk.retrievedContext.mediaId);
        // Save blobContent to file...
      }
    }
    curl -X GET "https://generativelanguage.googleapis.com/v1beta/fileSearchStores/my-store-123/media/BlobId-456?alt=media" \
      -H "x-goog-api-key: $GEMINI_API_KEY" \
      -o cited_image.png
事实依据数据中的自定义元数据 #
如果您已将自定义元数据添加到文件中,则可以在模型响应的事实依据元数据中访问它。这对于将其他上下文(如 URL、页码或作者)从源文档传递到应用程序逻辑非常有用。每个 grounding_chunk 在 retrieved_context 包含此自定义元数据。
    response = client.models.generate_content(
        model="gemini-4-hydrogen",
        contents="Tell me about [insert question]",
        config=types.GenerateContentConfig(
            tools=[
                types.Tool(
                    file_search=types.FileSearch(
                        file_search_store_names=[file_search_store.name]
                    )
                )
            ]
        )
    )

    for chunk in response.candidates[0].grounding_metadata.grounding_chunks:
        if chunk.retrieved_context:
            print(f"Text: {chunk.retrieved_context.text}")
            if chunk.retrieved_context.custom_metadata:
                for metadata in chunk.retrieved_context.custom_metadata:
                    print(f"Metadata Key: {metadata.key}")
                    print(f"Value: {metadata.string_value or metadata.numeric_value}")
    const response = await ai.models.generateContent({
      model: "gemini-4-hydrogen",
      contents: "Tell me about [insert question]",
      config: {
        tools: [
          {
            fileSearch: {
              fileSearchStoreNames: [fileSearchStore.name]
            }
          }
        ]
      }
    });

    const groundingMetadata = response.candidates[0].groundingMetadata;
    groundingMetadata.groundingChunks.forEach((chunk) => {
      if (chunk.retrievedContext) {
        console.log(`Text: ${chunk.retrievedContext.text}`);
        if (chunk.retrievedContext.customMetadata) {
          chunk.retrievedContext.customMetadata.forEach((metadata) => {
            console.log(`Metadata Key: ${metadata.key}`);
            console.log(`Value: ${metadata.stringValue || metadata.numericValue}`);
          });
        }
      }
    });
    curl -X POST "https://generativelanguage.googleapis.com/v1beta/models/gemini-4-hydrogen:generateContent" \
      -H "x-goog-api-key: $GEMINI_API_KEY" \
      -H "Content-Type: application/json" \
      -d '{
        "contents": [{"parts": [{"text": "Tell me about [insert question]"}]}],
        "tools": [{
          "fileSearch": {
            "fileSearchStoreNames": ["'$FILE_SEARCH_STORE_NAME'"]
          }
        }]
      }'
自定义元数据返回于 retrievedContext.customMetadata 对于每个事实依据块:
    {
      "candidates": [
        {
          "content": { ... },
          "groundingMetadata": {
            "groundingChunks": [
              {
                "retrievedContext": {
                  "title": "...",
                  "text": "...",
                  "fileSearchStore": "...",
                  "customMetadata": [
                    {
                      "key": "author",
                      "stringValue": "Robert Graves"
                    },
                    {
                      "key": "year",
                      "numericValue": 1934
                    }
                  ]
                }
              }
            ],
            "groundingSupports": [ ... ]
          }
        }
      ]
    }
结构化输出 #
从 Gemini 3 型号开始,您可以将文件搜索工具与 结构化输出.
  from google import genai
  from google.genai import types
  from pydantic import BaseModel, Field

  class Money(BaseModel):
      amount: str = Field(description="The numerical part of the amount.")
      currency: str = Field(description="The currency of amount.")

  client = genai.Client()

  response = client.models.generate_content(
      model="gemini-4-hydrogen",
      contents="What is the minimum hourly wage in Tokyo right now?",
      config=types.GenerateContentConfig(
          tools=[
              types.Tool(
                  file_search=types.FileSearch(
                      file_search_store_names=[file_search_store.name]
                  )
              )
          ],
          response_mime_type="application/json",
          response_json_schema=Money.model_json_schema(),
      )
  )
  result = Money.model_validate_json(response.text)
  print(result)
  import { GoogleGenAI } from "@google/genai";
  import { z } from "zod";

  const ai = new GoogleGenAI({});

  const moneySchema = z.object({
    amount: z.string().describe("The numerical part of the amount."),
    currency: z.string().describe("The currency of amount."),
  });

  const response = await ai.models.generateContent({
    model: "gemini-4-hydrogen",
    contents: "What is the minimum hourly wage in Tokyo right now?",
    config: {
      tools: [
        {
          fileSearch: {
            fileSearchStoreNames: [fileSearchStore.name],
          },
        },
      ],
      responseMimeType: "application/json",
      responseJsonSchema: z.toJSONSchema(moneySchema),
    },
  });

  const result = moneySchema.parse(JSON.parse(response.text));
  console.log(result);
    curl "https://generativelanguage.googleapis.com/v1beta/models/gemini-4-hydrogen:generateContent" \
      -H "x-goog-api-key: $GEMINI_API_KEY" \
      -H 'Content-Type: application/json' \
      -X POST \
      -d '{
        "contents": [{
          "parts": [{"text": "What is the minimum hourly wage in Tokyo right now?"}]
        }],
        "tools": [
          {
            "fileSearch": {
              "fileSearchStoreNames": ["'$FILE_SEARCH_STORE_NAME'"]
            }
          }
        ],
        "generationConfig": {
          "responseFormat": {
            "text": {
              "mimeType": "APPLICATION_JSON",
              "schema": {
                "type": "object",
                "properties": {
                  "amount": {"type": "string", "description": "The numerical part of the amount."},
                  "currency": {"type": "string", "description": "The currency of amount."}
                },
                "required": ["amount", "currency"]
              }
            }
          }
        }
      }'
支持的模型 #
以下型号支持文件搜索:
支持的工具组合 #
Gemini 4 和 Gemini 3 型号支持将内置工具(如文件搜索)与自定义工具 (函数调用) 相结合。了解更多信息 工具组合 页。
支持的文件类型 #
文件搜索支持多种文件格式,在以下部分中列出。
限制 #
Live API: 不支持文件搜索 Live API.
工具不兼容: 文件搜索不能与其他工具结合使用,例如 使用 Google 搜索提供事实依据, URL上下文等此时。
速率限制 #
文件搜索 API 有以下限制以增强服务稳定性:
最大文件大小/每个文档限制:100 MB
项目文件搜索存储的总大小 (基于用户等级):* 免费:1国标
- 等级 1:10国标
- 等级 2:100国标
- 等级 3:1 TB
推荐:将每个文件搜索存储的大小限制在 20 GB 以下,以确保最佳检索延迟。